

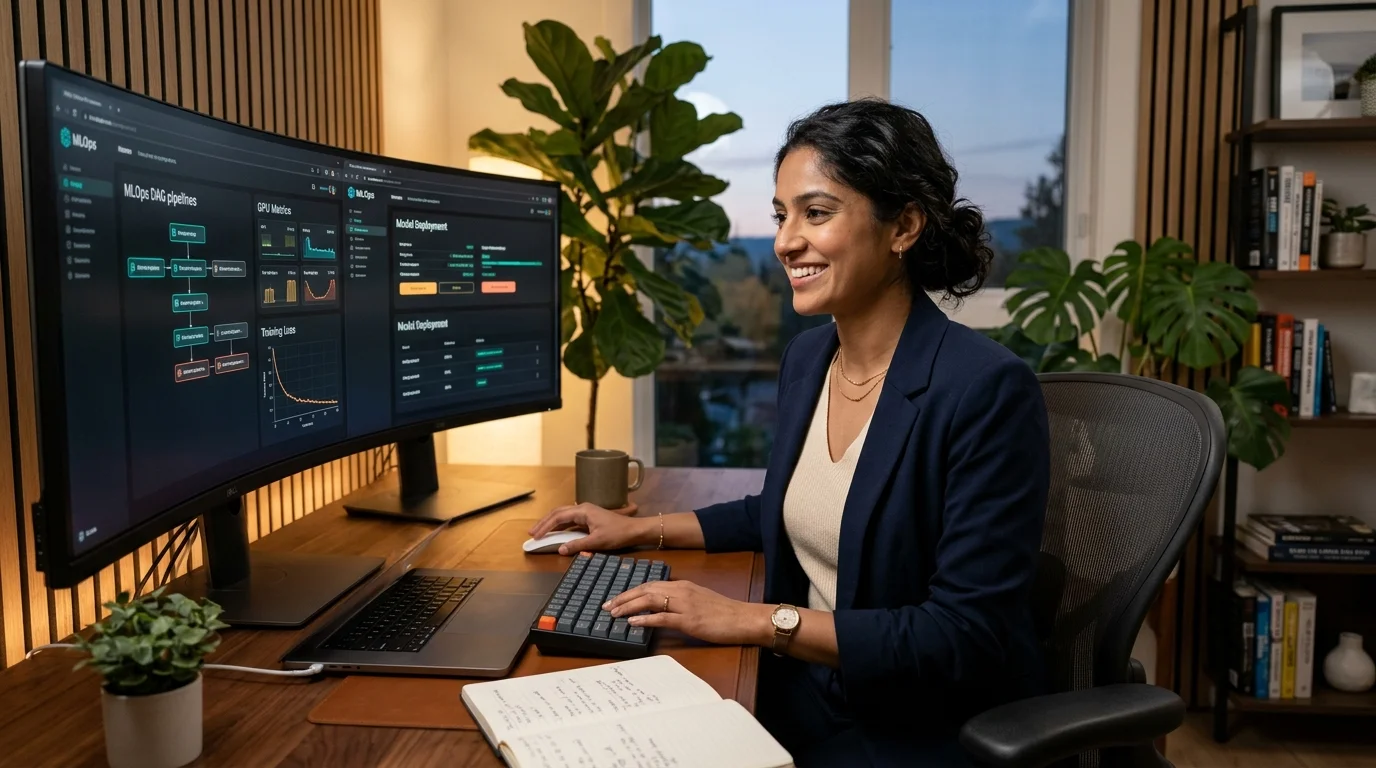
In 2026, enterprise artificial intelligence has reached an inflection point. Organizations are no longer evaluated simply on their ability to train a clever proof-of-concept in a Jupyter notebook; enterprise value is dictated by the ability to reliably deploy, scale, monitor, and continuously retrain machine learning models and large language models (LLMs) across global cloud infrastructures. Yet, industry data demonstrates that a majority of enterprise machine learning initiatives stall between prototype validation and production reliability. To bridge this critical engineering divide, technology enterprises and high-growth scale-ups worldwide are aggressively hiring specialized Machine Learning Operations (MLOps) Engineers.
Operating at the confluence of machine learning, platform engineering, and site reliability engineering (SRE), an MLOps Engineer provides the operational discipline required to turn fragile research models into highly available, low-latency, and cost-efficient cloud services. MLOps workflows are inherently location-independent: training pipelines, container registries, Kubernetes clusters, model registries, and drift detection monitors reside in centralized cloud environments and Git repositories accessible from anywhere in the world. As a result, distributed tech companies recruit MLOps talent globally, offering competitive international compensation packages ranging from $120,000 to $230,000+ USD alongside complete geographic freedom.
Drawing on insights from RemoteKraft's engineering career research—including our definitive guides to remote machine learning engineer jobs, remote AI engineer jobs, remote DevOps and cloud engineer jobs, remote platform engineer jobs, remote site reliability engineer jobs, remote data engineer jobs, remote technical interview preparation, and collaborating across remote time zones—this 2026 blueprint provides the technical roadmap, architectural patterns, portfolio frameworks, and compensation insights required to land elite worldwide remote MLOps roles.
1. MLOps Engineer vs. Machine Learning Engineer vs. DevOps: Defining the Boundaries
International hiring panels prioritize candidates who clearly articulate role boundaries across the modern machine learning lifecycle:
- Data Scientist / Applied Researcher: Focuses on statistical exploratory data analysis, mathematical formulation, feature hypothesis generation, and model experimentation. Discover more in our guide to remote data scientist jobs.
- Machine Learning Engineer (MLE): Specializes in model architecture design, distributed training optimization (FSDP, DeepSpeed), loss function engineering, and fine-tuning foundation weights. Read our complete guide to remote machine learning engineer jobs.
- MLOps Engineer (Infrastructure, Deployment & Observability): Builds automated CI/CD/CT (Continuous Integration, Continuous Delivery, Continuous Training) pipelines, manages GPU container orchestration on Kubernetes, provisions low-latency inference runtimes (vLLM, Triton), enforces model registries and governance, and tracks live model drift and degradation.
- DevOps / Platform Engineer: Manages underlying cloud infrastructure, VPC networking, general-purpose Kubernetes nodes, and standard software delivery toolchains without specialized ML hardware or lifecycle awareness. Compare roles in our guide to remote platform engineer jobs.
2. Core Technical Competencies Demanded by Global Remote Employers in 2026
To stand out in international remote technical screens, candidates must demonstrate hands-on mastery across six architectural pillars:
A. Automated Training Pipelines & Orchestration
Production ML requires deterministic, reproducible pipelines that convert raw ingested data into versioned model artifacts without manual intervention:
- Kubeflow Pipelines (KFP) & Argo Workflows: Designing declarative, DAG-based containerized pipeline steps that execute ETL, preprocessing, distributed training, and automated validation.
- MLflow & Weights & Biases: Tracking hyperparameter tuning sweeps, logging system hardware metrics, versioning source code commits against artifact checkpoints, and establishing formal staging-to-production promotion gates in model registries.
- Continuous Training (CT) Triggers: Implementing automated event-driven retraining pipelines triggered by data drift thresholds, scheduled chronologies, or upstream schema version increments.
B. Low-Latency Model & LLM Serving Infrastructure
Deploying models into production environments where hundreds of requests arrive per second requires deep runtime optimization:
- Specialized Inference Engines: Deploying high-throughput model servers including Triton Inference Server, vLLM, TGI (Text Generation Inference), and TensorRT-LLM for multi-GPU serving.
- Techniques for Hardware Efficiency: Implementing dynamic request batching, PagedAttention memory management, FP8/INT4 weight quantization (AWQ, GPTQ), and KV-cache optimization to maximize GPU token throughput while minimizing infrastructure costs.
- REST & gRPC Serving Frameworks: Packaging lightweight real-time microservices using FastAPI, BentoML, and Ray Serve with strict concurrency limits and p99 latency guarantees.
C. Kubernetes & GPU Resource Orchestration
Kubernetes is the ubiquitous operating system for distributed machine learning workloads. Remote MLOps engineers must demonstrate advanced cluster orchestration capabilities:
- GPU Node Management: Configuring NVIDIA GPU operators, dynamic resource allocation (DRA), multi-instance GPU (MIG) partitioning, and spot instance interruption handling for training jobs.
- KEDA & Autoscaling: Implementing custom metric horizontal pod autoscalers (HPA) using KEDA to autoscale inference pods based on request queue depth or GPU memory pressure rather than generic CPU utilization.
- Helm & GitOps: Managing cluster infrastructure declaratively using Terraform, Helm charts, and ArgoCD or Flux for automated drift reconciliation.
D. Feature Stores & Real-Time Data Architectures
One of the primary failure modes in machine learning systems is training-serving skew—where features calculated during batch training differ subtly from features calculated in real-time inference:
- Feast & Hopsworks: Defining unified feature views that serve low-latency key-value lookups from online stores (Redis, DynamoDB) during real-time prediction and point-in-time correct joins from offline stores (Snowflake, BigQuery, Parquet on S3) during model training.
- Streaming Feature Ingestion: Ingesting high-velocity event streams via Kafka, Apache Flink, or Redpanda to update real-time user session aggregations within milliseconds.
E. Model Observability, Drift Detection & LLMOps Governance
Unlike traditional software that fails with explicit HTTP 500 error codes, machine learning models degrade silently as real-world distributions evolve:
- Statistical Drift Monitoring: Utilizing tools like Evidently AI or Whylabs to monitor Kolmogorov-Smirnov (KS) tests, Population Stability Index (PSI), and Wasserstein distance on input features and predicted distributions.
- LLM Observability & Evals: Tracking token consumption costs, latency percentiles, hallucination rates, and prompt injection attempts using Langfuse, Arize Phoenix, and automated evaluation frameworks (Ragas, TruLens).
- Shadow & Canary Deployments: Implementing traffic-mirroring and blue-green deployments via service meshes (Istio, Envoy) to evaluate candidate models against live production traffic before full cutover.
F. Data Security, Compliance & MLOps DevSecOps
International organizations operating across jurisdictions must maintain strict governance over proprietary datasets and trained model weights:
- Weight Security & Supply Chain Integrity: Enforcing cryptographic signing of model artifacts (Sigstore, Cosign) and vulnerability scanning of base container images. Review security best practices in our remote DevSecOps engineer guide.
- Data Privacy & PII Scrubbing: Automated redaction of sensitive personal identifiable information (PII) before training or fine-tuning runs to ensure compliance with GDPR, HIPAA, and SOC 2 Type II regulations.
3. The Distributed Advantage: Why Global Companies Rely on Remote MLOps Teams
In distributed engineering organizations operating across multiple continents, asynchronous discipline is critical. When a mission-critical fraud detection model or generative customer assistant experiences sudden latency spikes or inference failures at 2:00 AM UTC, distributed teams cannot rely on ad-hoc hallway coordination.
Remote MLOps engineers build self-healing, transparent operational ecosystems. By standardizing automated continuous deployment pipelines, reproducible infrastructure-as-code manifests, and automated rollback triggers, international teams can deploy model updates with complete confidence around the clock. To master asynchronous workflows, read our practical guide on collaborating smoothly across global remote time zones.
4. Designing a High-Impact Remote MLOps Portfolio
Because enterprise models and proprietary corporate datasets cannot be shared publicly, building well-documented, open-source proof-of-work repositories is the single most effective way to validate your seniority to international engineering hiring managers:
- End-to-End LLMOps Fine-Tuning & Serving Pipeline: Build a GitHub repository demonstrating automated LoRA/QLoRA parameter-efficient fine-tuning on an open-weights foundation model. Include automated synthetic evaluation in GitHub Actions, containerized deployment via vLLM with streaming endpoints, and a live web demo interface.
- Real-Time Feature Store & Drift Remediation Architecture: Create a reproducible Docker Compose or local Kind (Kubernetes in Docker) cluster featuring Feast, Redis, PostgreSQL, and Evidently AI. Simulate a deliberate real-world data drift scenario and demonstrate automated alerts and fallback inference paths.
- Terraform & Helm GPU Inference Repository: Author infrastructure-as-code deploying an autoscaling inference deployment on AWS (EKS) or GCP (GKE) with custom Prometheus metrics, dynamic batching, and Grafana dashboards tracking GPU temperature, VRAM consumption, and p95 token latencies.
- Architecture Post-Mortem & Cost Optimization Case Study: Publish a technical markdown retrospective explaining how you cut cloud inference costs (e.g., "How we reduced production LLM inference latency by 64% and cut monthly AWS GPU spend by $18,000 using TensorRT-LLM and dynamic batching").
5. Worldwide Remote Compensation Benchmarks for MLOps Engineers (2026)
Because MLOps blends high-demand machine learning expertise with mission-critical cloud platform engineering, international compensation packages for remote MLOps engineers rank among the highest in software engineering:
| Geographic Region | Mid-Level Range (USD) | Senior / Lead Range (USD) | Standard Hiring Structure |
|---|---|---|---|
| United States & Canada | $140,000 – $185,000 | $185,000 – $240,000+ | Direct W-2 / 1099 Contractor |
| Western Europe & UK | $90,000 – $130,000 | $130,000 – $180,000+ | Local Entity / EOR (Employer of Record) |
| Latin America (LATAM) | $70,000 – $105,000 | $105,000 – $155,000+ | USD International Contractor (B2B) |
| India & South Asia | $60,000 – $95,000 (₹50L – ₹80L) | $95,000 – $160,000+ (₹80L – ₹1.35Cr+) | Direct USD Contractor / EOR / Indian Entity |
| Eastern Europe & Baltics | $65,000 – $100,000 | $100,000 – $145,000+ | B2B Sole Proprietor / EOR |
Note: Figures represent base salary plus guaranteed performance bonuses. In early-stage startups and high-valuation AI companies, equity grants can represent an additional 20% to 40% of overall earnings. To structure your international agreements cleanly, review our guide on comparing global contractor versus employee models.
6. Navigating Remote Technical Interviews for MLOps Roles
International hiring processes for MLOps engineers typically consist of four evaluation rounds:
- Initial Engineering Recruiter Screen (30 mins): Evaluation of communication clarity, timezone overlap capacity, and experience managing cloud infrastructure. Review our guide to preparing for remote technical interviews.
- Systems & Coding Assessment (60 mins): Practical coding focusing on data manipulation in Python (NumPy, PyTorch, Pandas), Docker containerization, and API construction using FastAPI.
- MLOps Architecture & System Design (60–75 mins): Designing an end-to-end production ML system—for instance, architecting a real-time recommendation engine with sub-50ms latency, handling data drift detection, and managing blue-green deployments on Kubernetes.
- Asynchronous Take-Home or Portfolio Deep Dive: Demonstrating working knowledge of deployment manifests, pipeline definitions, and monitoring setups. Learn how to excel in take-home evaluations with our take-home assignment playbook.
7. Frequently Asked Questions (FAQ)
Do remote MLOps Engineers need advanced mathematics or PhD backgrounds?
No. While academic PhDs are valued in research teams creating novel foundational model architectures, MLOps is an applied systems engineering discipline. International tech employers prioritize demonstrable software engineering habits, Kubernetes proficiency, GPU optimization skills, and production reliability over theoretical proofs.
Can a DevOps or Cloud Engineer transition into MLOps?
Yes. Platform and DevOps engineers are ideally positioned to transition into MLOps. To make the transition, focus on understanding the unique characteristics of machine learning lifecycles: non-deterministic outputs, GPU resource scheduling, model registries, feature stores, and statistical drift detection. Pair your existing Kubernetes and Terraform skills with MLflow, vLLM, and Kubeflow.
How can international candidates protect themselves from remote job scams?
Given the intense demand for AI and MLOps roles, fraudulent job postings are common. Legitimate remote employers will never require upfront equipment purchase payments, request confidential banking credentials during screening, or conduct interviews exclusively through untraceable chat apps. Protect your search with our definitive guide on spotting and avoiding remote job scams.
Ready to deploy cutting-edge machine learning and generative AI architectures for top international technology employers? Discover verified worldwide remote openings on RemoteKraft's remote job marketplace, optimize your technical resume using our free ATS-friendly online resume builder, and secure your next elite remote MLOps role today.
.png)
