

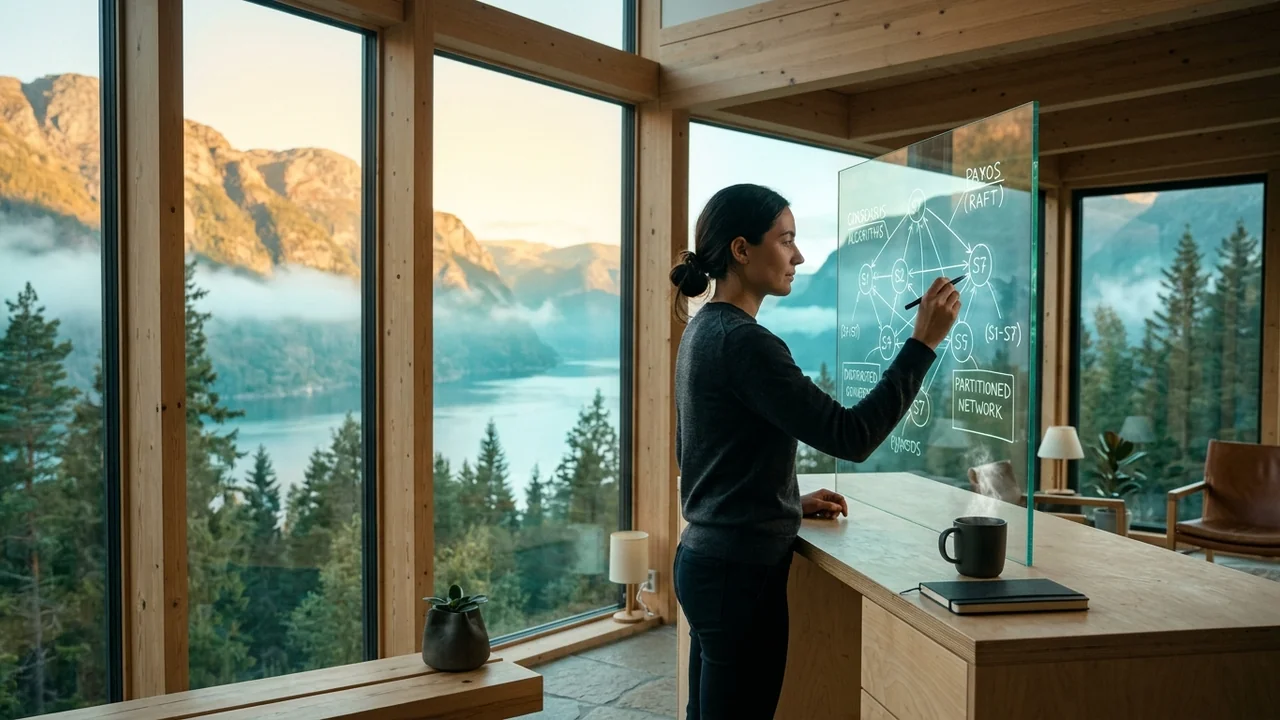
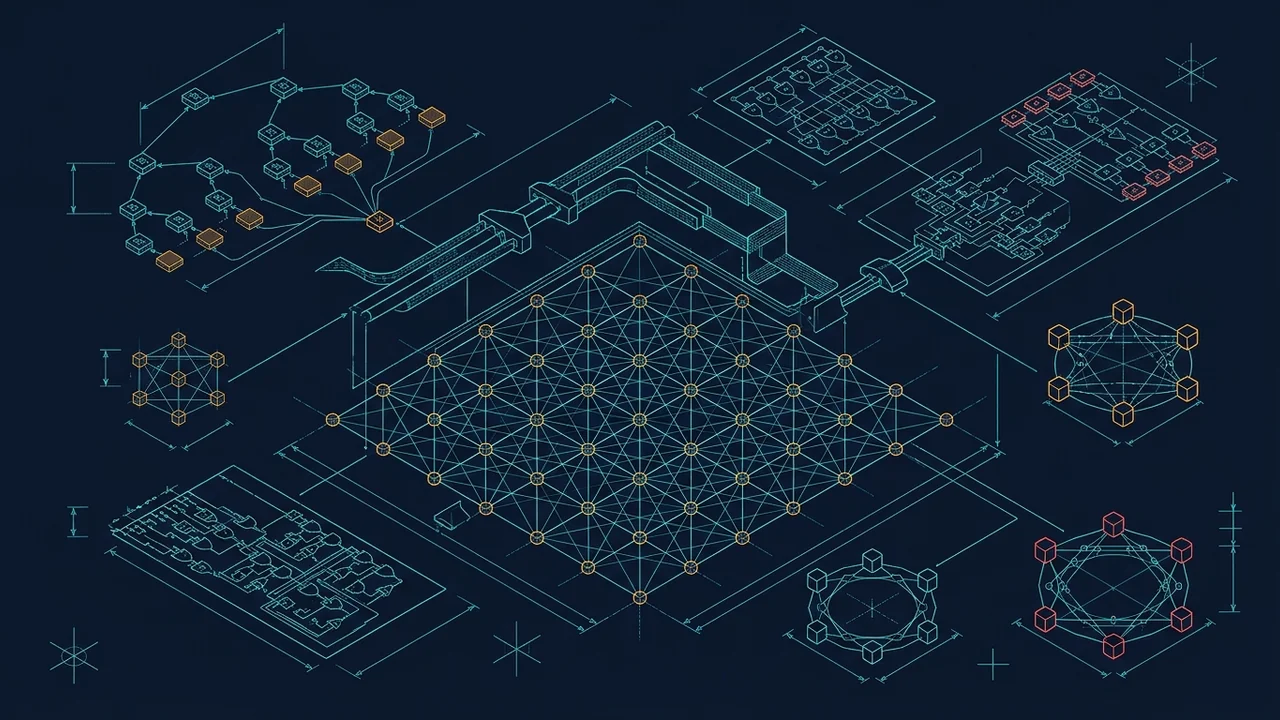
In 2026, enterprise software architectures operate on a planetary scale. Modern consumer applications, artificial intelligence inference pipelines, financial settlement networks, and real-time collaborative workspaces no longer run on single monolithic servers. Instead, they run across thousands of coordinated, geo-replicated compute nodes spanning multi-cloud regions and edge locations. Building and operating systems at this scale requires solving fundamental computing problems: achieving consensus across untrusted networks, coordinating state machines without single points of failure, handling network partitions gracefully, and ensuring low-latency data replication.
Because distributed systems engineering addresses logical coordination over asynchronous networks rather than physical hardware colocation, it is one of the most naturally remote-first disciplines in the technology industry. International tech giants, high-growth infrastructure startups, database vendors, and cloud providers actively recruit Remote Distributed Systems Engineers worldwide. Whether you are implementing the Raft consensus protocol in Rust from a quiet coastal home office or optimizing Kafka streaming pipelines in Go across asynchronous time zones, worldwide companies offer competitive USD compensation packages ranging from $140,000 to $280,000+ alongside location independence.
Synthesizing insights from RemoteKraft's remote career intelligence platform—including our technical career blueprints for remote backend developer jobs, remote cloud architect jobs, remote database engineer jobs, remote platform engineer jobs, remote site reliability engineer jobs, remote software architect jobs, remote blockchain engineer jobs, remote technical interview preparation, and our guide to asynchronous remote time zone collaboration—this 2026 guide provides the definitive blueprint to mastering distributed systems competencies, showcasing verifiable proof-of-work, acing international system design interviews, and negotiating premier global compensation.
1. Distributed Systems Engineer vs. Backend Developer vs. Cloud Architect vs. Site Reliability Engineer (SRE)
Hiring committees at international infrastructure and tech companies evaluate candidates based on their understanding of architectural boundaries and specialized engineering responsibilities:
- Remote Distributed Systems Engineer: The architect of consensus, state synchronization, and fault-tolerant primitives. Writes high-performance low-level code (Go, Rust, C++, Java) to build distributed databases, consensus engines (Raft, Paxos), message brokers, stream processing engines, and distributed file systems. Solves foundational problems around linearizability, quorum reads/writes, clock drift, network partitioning, and split-brain mitigation.
- Traditional Backend Developer: Builds business domain services, HTTP/gRPC APIs, and application workflows that consume existing databases and caches. While backend engineers leverage relational databases (PostgreSQL) and key-value stores (Redis) as dependable black boxes, distributed systems engineers design the internal storage engines, replication algorithms, and consensus layers that make those databases reliable. Compare core backend skills in our guide to remote backend developer jobs.
- Cloud / Solutions Architect: Designs high-level cloud topologies, service boundaries, and infrastructure integration across public clouds (AWS, GCP, Azure). Focuses on cost optimization, multi-region routing, security perimeters, and managed services rather than implementing low-level socket networking, memory-mapped storage engines, or consensus protocols. Explore cloud architecture fundamentals in our guide to remote cloud architect jobs.
- Site Reliability Engineer (SRE): Specializes in operational observability, incident response, SLI/SLO tracking, automated failover verification, and production infrastructure stability. While SREs ensure distributed platforms remain online and resilient during production incidents, distributed systems engineers write the software that handles partial network partitions and Byzantine faults autonomously. Review operational competencies in our guide to remote site reliability engineer jobs.
2. Core Technical Pillars Demanded by Global Remote Employers in 2026
To win competitive worldwide remote offers and earn top-tier USD salaries, distributed systems engineers must demonstrate deep theoretical comprehension coupled with rigorous systems programming capability across five foundational pillars:
A. Consensus Mechanics, Quorum Replication & Leader Election
At the heart of every mission-critical distributed platform lies a consensus mechanism ensuring that multiple nodes agree on a deterministic sequence of state machine transitions:
- The Raft Consensus Algorithm: Deep understanding of leader election, heartbeat intervals, randomized election timeouts, log replication, commit index advancement, and safety invariants. Implementing joint consensus for cluster membership changes and log compaction via snapshots.
- Paxos & Multi-Paxos: Understanding Synod consensus, prepare/promise phases, accept/accepted cycles, and leader-based Multi-Paxos optimizations utilized in enterprise platforms like Google Spanner and Apache ZooKeeper.
- Quorum Protocols & Read/Write Dynamics: Mastering Dynamo-style quorum mathematics (R + W > N), read repair, sloppy quorums with hinted handoff, and anti-entropy synchronization using Merkle trees.
- Split-Brain Prevention: Implementing fencing tokens, epoch numbers, generation IDs, and witness nodes to ensure network partitions cannot result in conflicting state writes.
B. High-Throughput Event Streaming & Stream Processing
Modern distributed systems treat data as an unbounded, continuous stream of immutable events rather than static tables:
- Log-Structured Storage & Distributed Brokers: Mastering the mechanics of Apache Kafka and Redpanda, including partition assignment strategies, consumer group rebalancing protocols, zero-copy socket transfers (sendfile), OS page cache utilization, and segment index pruning.
- Stream Processing Engines (Apache Flink): Designing stateful stream computations with Apache Flink. Understanding event time vs. processing time, watermarks, sliding and tumbling windows, checkpointing via Chandy-Lamport distributed snapshots, and exactly-once processing guarantees.
- Change Data Capture (CDC): Streaming relational database write-ahead logs (WAL) into event backbones using Debezium to synchronize distributed microservices without dual-write consistency anomalies.
C. Distributed State, Consistency Models & Partitioning Tradeoffs
Handling data across nodes requires choosing the appropriate consistency model based on system requirements:
- CAP Theorem & PACELC Theorem: Rigorous evaluation of trade-offs. PACELC states: if there is a Partition (P), how does your system trade off Availability (A) and Consistency (C); Else (E), how does it trade off Latency (L) and Consistency (C)?
- Consistency Spectra: Clear comprehension of linearizability (strict serializability), sequential consistency, causal consistency, and eventual consistency. Knowing when strong consistency is essential (financial ledgers) vs. when eventual consistency provides superior throughput and availability.
- Conflict-Free Replicated Data Types (CRDTs): Implementing state-based (CvRDT) and operation-based (CmRDT) CRDTs (LWW-Element-Set, PN-Counter, RGA text trees) to enable seamless local-first collaboration and multi-region conflict resolution without central coordinator locks.
- Logical Clocks & Vector Clocks: Replacing unreliable physical wall-clock timestamps with Lamport timestamps, Vector Clocks, and hybrid logical clocks (HLC) to establish strict causal event ordering across asynchronous networks.
D. Systems Languages & High-Performance Concurrency
Distributed infrastructure code must squeeze maximum efficiency from CPU caches, memory bandwidth, and non-blocking network I/O:
- Go (Golang): The industry standard for cloud-native infrastructure (Kubernetes, etcd, Docker). Mastering goroutine scheduling, channel semantics, memory pool reuse (sync.Pool), context propagation, race condition detection, and pprof CPU/memory profiling.
- Rust: Rapidly becoming the dominant language for next-generation storage engines and data platforms (Redpanda, TiKV, Polars). Leveraging ownership semantics, zero-cost abstractions, fearless concurrency, and asynchronous runtimes like Tokio (epoll/kqueue event loops, pinning, actors).
- Non-Blocking Network I/O & Serialization: Building ultra-fast network protocols utilizing Protobuf, gRPC, FlatBuffers, and io_uring to eliminate kernel-user space memory copying.
E. Chaos Engineering, Fault Injection & Formal Verification
In distributed environments, catastrophic failures occur regularly: packet loss, asymmetric network partitions, disk stalls, and memory corruption:
- Jepsen Analysis: Understanding Kyle Kingsbury's Jepsen framework to test distributed systems under partition injection, clock skews, process pauses, and node crashes to verify linearizability and uncover hidden split-brain bugs.
- Formal Specification with TLA+: Writing formal mathematical specifications in TLA+ or PlusCal to model consensus algorithms, verify state transition safety invariants, and eliminate subtle race conditions before writing a single line of production code.
- Deterministic Simulation Testing: Building simulation testing engines (inspired by FoundationDB and TigerBeetle) where time, network delays, and disk faults are simulated deterministically to reproduce complex multi-node bugs in milliseconds.
3. Structuring a Standout Proof-of-Work Portfolio for Remote Hiring
International hiring managers evaluating candidates across different continents rarely prioritize university degrees or resume buzzwords. They search for undeniable proof of engineering craftsmanship through open-source code and public technical writing:
- Custom Raft Consensus Implementation: Build an open-source, fully functional implementation of the Raft protocol in Go or Rust. Include leader election, log replication, snapshotting, and dynamic cluster membership changes. Demonstrate deep competence by writing automated test suites that simulate dropped packets and network splits.
- Distributed Key-Value Store: Create a replicated, sharded key-value store featuring consistent hashing with virtual nodes, vector clock conflict resolution, and quorum read/write consistency. Document architecture decisions in clean Markdown ADRs (Architectural Decision Records).
- Jepsen Test Verification: Set up an open-source Jepsen test suite against a popular open-source database or your custom project. Documenting how you uncovered or verified consistency invariants under severe network partitions immediately elevates your candidacy to the top tier.
- Open-Source Contributions to Major Infrastructure: Contribute bug fixes, performance optimizations, or documentation improvements to high-impact distributed projects such as etcd, TiKV, Apache Kafka, Apache Flink, CockroachDB, or OpenTelemetry. A merged pull request in an enterprise distributed repository serves as universal proof of competence.
4. Worldwide Remote Distributed Systems Engineer Compensation Benchmarks (2026)
Because distributed systems expertise is rare and foundational to high-scale enterprise operations, global employers offer substantial compensation packages. International remote professionals frequently negotiate direct USD compensation regardless of geographic location:
| Experience Tier | Key Competencies & Scope | Worldwide Remote Range (USD) |
|---|---|---|
| Mid-Level Distributed Systems Engineer (3–5 yrs) | Go or Rust proficiency, understanding of consensus protocols, multi-threaded concurrency, Kafka partitioning, gRPC communication, and metric observability. | $140,000 – $180,000 |
| Senior Distributed Systems Engineer (5–8 yrs) | Autonomous implementation of consensus algorithms (Raft), storage engine internals (LSM-trees, B-trees), Jepsen testing, Flink stream pipelines, and zero-downtime cluster upgrades. | $180,000 – $230,000 |
| Staff / Principal Distributed Systems Engineer (8+ yrs) | Global multi-region topology design, TLA+ formal verification, core storage engine architecture, extreme throughput optimization (io_uring), technical mentorship, and cross-team RFC leadership. | $230,000 – $290,000+ |
International hiring structures vary between direct full-time employment via Employers of Record (EOR) like Deel or Remote, and cross-border B2B contractor agreements. Read our comprehensive analysis on global remote employee versus contractor hiring models and our guide to worldwide remote salary negotiation strategies to optimize your international contracts and tax structures.
5. Mastering Asynchronous Architecture Communication
In distributed engineering organizations, technical execution is only half the battle. Because distributed systems teams operate across asynchronous time zones spanning the Americas, Europe, and the Asia-Pacific region, clear written communication is a primary hiring criterion:
- RFC (Request for Comments) Culture: Documenting system design proposals in exhaustive written RFCs before building. Outlining API schemas, failure modes, CAP trade-offs, network partition handling, and rollback plans for global peer review.
- Blameless Post-Mortems: Analyzing production distributed failures (such as cascading timeouts, thundering herds, or partition-induced failovers) with mathematical objectivity, documenting timeline reconstructions and systemic guardrails.
- Asynchronous Collaboration Discipline: Providing crystal-clear GitHub pull request descriptions, reproducing race conditions with deterministic unit tests, and structuring daily updates asynchronously to keep global teammates synchronized. Explore best practices in our guide to managing time zones in remote work.
6. Frequently Asked Questions (FAQs)
Do I need an advanced degree in computer science to work as a Distributed Systems Engineer?
No. While distributed systems is an academically rich field with seminal papers (Lamport, Brewer, Ousterhout), commercial remote hiring teams value hands-on systems programming skills and demonstrable proof-of-work above academic credentials. Candidates who can write clean, concurrent Go or Rust code, explain how Raft handles split-vote scenarios, and demonstrate familiarity with Jepsen testing regularly beat candidates with theoretical degrees who lack production coding proficiency.
What programming languages are most valuable for remote distributed systems roles?
Go and Rust dominate the modern distributed systems landscape. Go powers cloud-native infrastructure (Kubernetes, Docker, etcd, Nomad, CockroachDB), making it the most broadly demanded language. Rust is preferred for performance-critical storage engines, consensus frameworks, and next-generation message brokers where zero-cost abstractions and memory safety without garbage collection pauses are paramount. C++ and Java remain heavily utilized in legacy enterprise search and data infrastructure (Hadoop, Kafka, Cassandra).
How should I prepare for distributed systems technical interview loops?
Expect a multi-stage technical evaluation: a coding assessment focusing on concurrency primitives (mutexes, channels, reader-writer locks, worker pools), a distributed system design interview (e.g., design a distributed key-value store, a globally unique ID generator, or an event-driven pub/sub broker), and an architecture deep-dive into past production failures. Review our comprehensive preparation guide to remote technical interview preparation.
Ready to build the high-throughput, fault-tolerant infrastructure powering global digital economies from the comfort of your home office? Explore verified worldwide listings on RemoteKraft's remote job board, check out our specialized distributed systems engineer jobs category, optimize your technical resume using our free online resume builder, and launch your high-impact worldwide remote career today.
.png)
